For Authorizers & Application Evaluators
Every charter application, read in full and cited to the page.
CharterRead.ai is the evidence-grounded AI charter application evaluation solution. You submit your application rubric and the charter applications; our platform generates in-depth analyses of each application.
How it works
Submit your rubric
We load your authorizing office's own published application rubric, so every evaluation is scored against your standards.
Upload applications
Full charter applications with attachments, hundreds of pages at a time. Every page is read; nothing is sampled or excerpted.
Get in-depth analyses
Question-by-question findings with page citations, capacity-interview questions built from the gaps, and recommendations for the review team.
Why not just paste the application into ChatGPT or Claude?
The short answer: our system is much better at giving the same results on Tuesday as on Wednesday, because there is a system through which the analyses are processed. Here's the more detailed answer.
CharterRead.ai reads the whole application. Every page, every question.
A charter application and its attachments run hundreds of pages. Anyone using ChatGPT, Claude, or any general-purpose chatbot is pasting excerpts and reviewing what they pasted.
CharterRead.ai scores against your rubric, not a general idea of a good school.
We load the authorizer's own published rubric and evaluate question by question against it. A general-purpose chatbot evaluates against its impression of quality. This holds for ChatGPT, Claude, and Gemini alike, even in advanced use.
Every rating points to the page it came from.
Each finding cites the page in the application it's based on, so a disagreement takes seconds to settle. A chatbot either gives no citation or invents one, and an authorizer who gets burned once by a fabricated citation never trusts it again.
The gaps become the interview questions.
CharterRead.ai generates capacity-interview questions from the specific weaknesses it found in an application, not from a standard bank.
Your documents stay yours.
Pre-release applications don't go into a consumer chatbot's history. Materials sit in the authorizer's own workspace, we have a data processing agreement developed with an education partner, exports are redacted so they can go to a board, and our AI provider's terms prohibit training on the content.
See a real evaluation
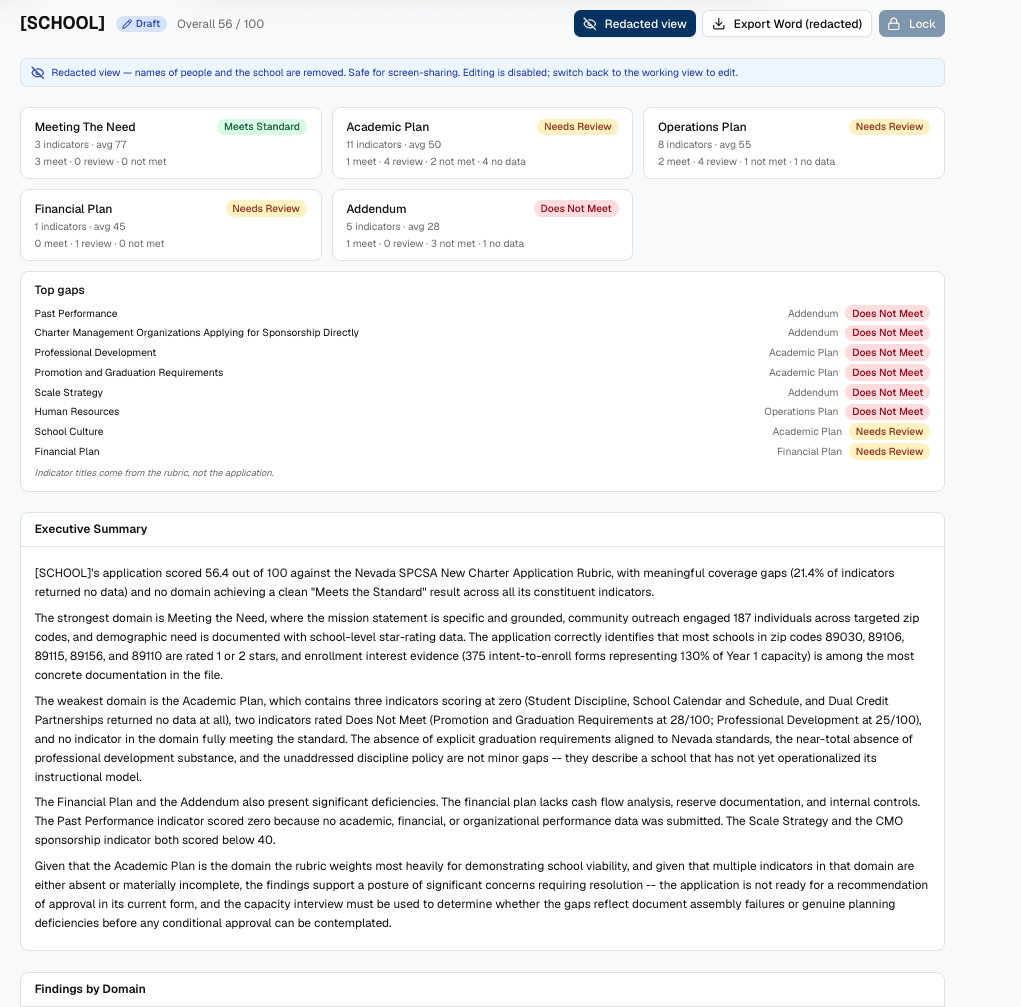
From an actual charter application evaluation, shown in the redacted view with the school's and all individuals' names removed.
One evaluation, the whole picture
Domain-by-domain scoring against your rubric, the top gaps ranked, and an executive summary a review team can take straight into deliberation. The redacted view removes names of people and the school, so it's safe to share.
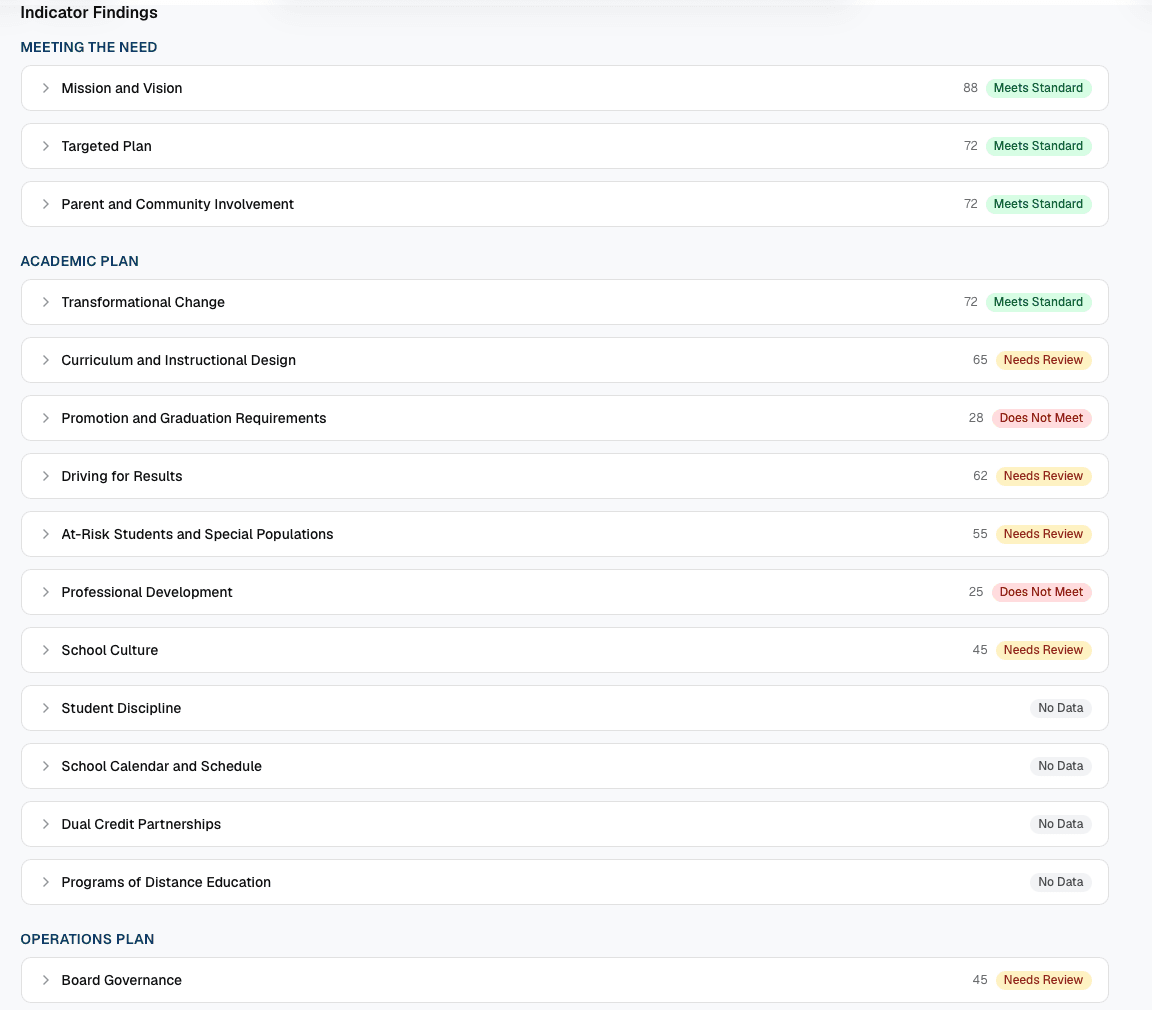
Question by question, against your rubric
Every rubric indicator gets its own finding and status. Sections the application never addressed are marked No Data instead of being quietly skipped, so omissions are visible at a glance.
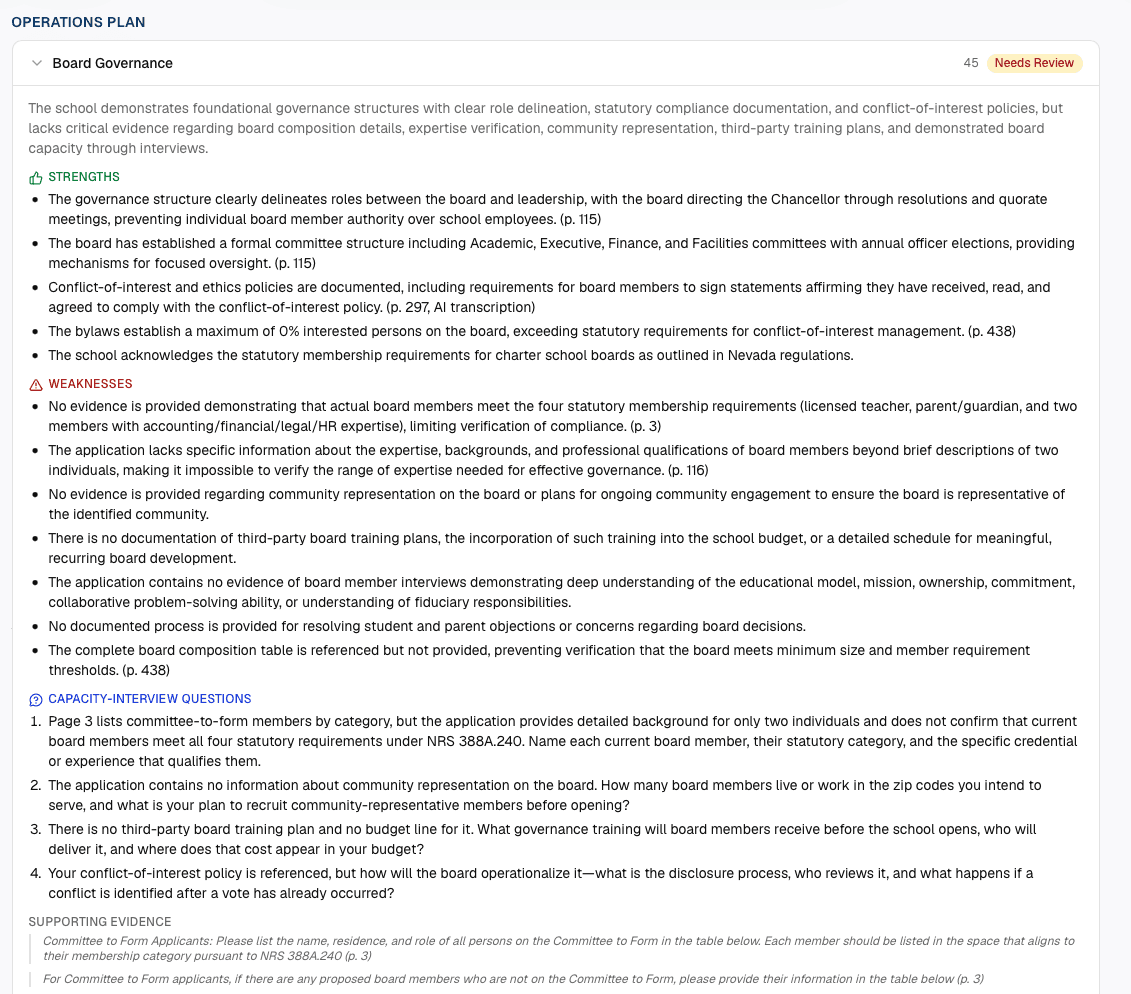
Strengths, weaknesses, and the questions to ask
Each finding lays out strengths and weaknesses with page citations, then turns the specific gaps into capacity-interview questions your team can use as written.
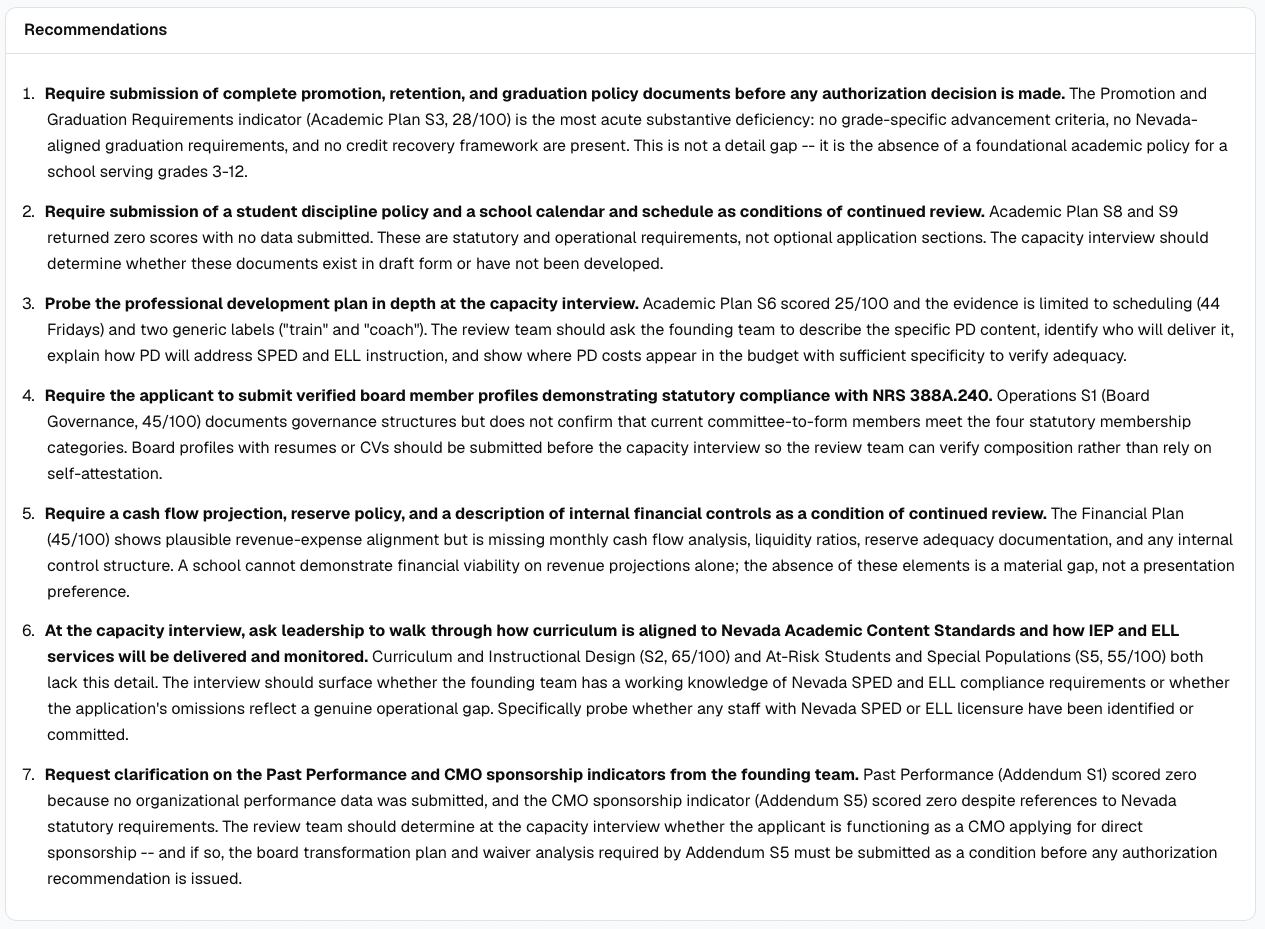
Recommendations your team can act on
The evaluation closes with concrete recommendations: what to require before a decision, what to probe at the capacity interview, and where the application needs clarification.
Pricing
$299
per application
A complete evaluation of one charter application and its attachments, against your rubric.
$999
one-time setup
We load and calibrate your published rubric as your evaluation framework. Charged once, not per cycle.
Invoiced per cycle. No subscription, and no self-serve signup — we set your framework up with you before your first evaluation.
Questions authorizers ask
Whose rubric do you evaluate against?+
Yours. We load your authorizing office's own published application rubric as the indicator set, and every finding is scored against it question by question. That is the $999 one-time setup.
How long does an evaluation take?+
A full application, attachments included, comes back the same day in normal conditions. The bound is our processing, not your reviewers' calendars.
Can I check a finding I disagree with?+
That is the point of the citations. Every rating names the page it came from, so a contested finding is settled by opening the application to that page rather than by re-reading it.
What happens to our applications?+
They stay in your workspace. We work under a data processing agreement developed with an education partner, exports are redacted so they can go to a board, and our AI provider's terms prohibit training on the content.
Does this replace our reviewers?+
No. It gives a review team a complete, cited first pass and the interview questions that follow from it. Deliberation and the decision stay with the authorizer.
What if an application never addresses a rubric question?+
It is marked No Data rather than quietly scored low, so omissions are visible instead of being buried in an average.
From the team behind SchoolQualityReview.ai
Two products, one team, one platform. SchoolQualityReview.ai evaluates operating schools against quality frameworks; CharterRead.ai evaluates the applications to open one. Same evidence-grounded engine, same data handling, same citations.
Visit SchoolQualityReview.ai →Bring it to your next application cycle
Tell us about your rubric and your cycle, and we will walk you through a real evaluation.
Contact us to get started